A stalled offshore project is rarely broken where the client thinks it is. Before anyone writes a line of code, find out who controls the accounts, whether the thing builds at all, and how much of it anyone still understands.
The month divides into four bands, and each one answers a single question.
| Days | The question it answers | What you hold at the end |
|---|---|---|
| 1-3 | Do you control your own project? | An access inventory, and rotated credentials wherever you are entitled to rotate them |
| 4-10 | What do you actually have? | Audit findings, and a build that either reproduces or does not |
| 11-20 | What survives? | A written decision on what to repair and what to rebuild |
| 21-30 | Can the new team ship? | One change in production, and a measured baseline |
First, name the failure
Four different problems arrive looking the same. A project that is late, quiet and over budget might be failing in its control, its knowledge, its code or its delivery, and each one has a different first move. Guessing wrong costs two weeks you do not have.
A control failure means you cannot get at the work at all, because the accounts, the repository or the rights to it sit with someone else. A knowledge failure means nobody who understands the system is still reachable. A code failure means the work that exists does not hold together. A delivery failure means the work exists but never reaches users, and nobody can say what is finished.
Control outranks the other three. You cannot audit a codebase you cannot clone, and you cannot fix a deployment you cannot reach. The first question is not how bad the code is. It is what you actually hold.
| What you are seeing | What has probably failed | Where the work lands |
|---|---|---|
| The vendor holds the accounts or the repository | Control | Days 1-3 |
| The developers who built it have left | Knowledge | Days 4-10 |
| Each new feature breaks an old one | Code | Days 4-10, then 11-20 |
| Nobody can say what is finished | Delivery | Days 4-10 |
| Demos work, nothing reaches production | Delivery | Days 21-30 |
A stalled project can have several of these running at once. Rank them by which one blocks the others: control comes first because nothing else is possible without it, then knowledge, then the code, then delivery. Whatever the table says, days 1-3 run regardless, because an access inventory is worth having even on a project that turns out to be healthier than it looked.
Days 1-3: Get the accounts back
Inventory every account the project touches, and record who holds the top-level rights to each one. Not who has access, which is a longer and less useful list. Who can remove everybody else.
| System | What you need to hold | The common failure |
|---|---|---|
| Source control | Ownership of the organization, not a seat in it | The repository lives in the vendor's organization |
| Cloud hosting | Root or billing owner on the account | The account is in the vendor's name |
| Domain and DNS | Registrar login, and the transfer lock status | Registered to a departed developer's email |
| App stores | Owner of the developer account | The listing belongs to the vendor |
| CI and builds | Admin on the pipeline, plus the signing keys | Signing keys exist only on one build machine |
| Secrets | The production values, wherever they are kept | A single developer's local environment file |
| Error and log tools | Admin, and the data retention window | A trial account whose history has already expired |
| Analytics and payments | Owner, and every live API key | Keys shared across several of the vendor's clients |
Then rotate, within limits. Removing a vendor from a dashboard does not invalidate the keys they already copied, and a key nobody turns off does not expire on its own. In its State of Secrets Sprawl 2026 report, GitGuardian found that nearly 70% of credentials confirmed valid in 2022 were still valid in January 2025, and that the figure remained above 64% in January 2026 (GitGuardian, March 2026). A credential nobody rotated is a credential that still works.
Two limits decide how far you can take this. Rotate every credential on an account you own outright. Where an account is still in the vendor's name, as the table above says it often is, the contract settles the question before you touch anything, because locking someone out of their own account is a different act in law from securing your own.
The second limit is operational. The inventory records who owns each account, not what consumes each key, and a project you inherited yesterday has integrations nobody has mapped. Work out what each credential is used by, rotate in stages rather than all at once, and keep the old value recoverable until the replacement is confirmed working.
Assume secrets are sitting in the repository itself. The same report counted 28.65 million new hardcoded secrets added to public GitHub commits during 2025, a 34% rise year over year, and found internal repositories roughly six times more likely than public ones to contain at least one. An internal repository is the likelier place to find a live database password, not the safer one.
Look outside the code as well. GitGuardian attributed 28% of the incidents it saw to material that never touched source control at all, in tools such as Slack, Jira and Confluence. Search the project's chat history for the word "password" before deciding the repository is the whole of your exposure.
While the inventory is running, read the contract. Four things matter now: who owns the code as written, whether payment is a condition of that ownership, what notice the termination clause requires, and whether the agreement puts a copy of the source in escrow. Who owns the code in offshore software work covers the first two, which are the ones that decide whether you can act at all.
Treat any escrow arrangement with less confidence than the contract implies. A deposit is only as current as the last time somebody made one, and release conditions tend to be written around a vendor going out of business rather than a relationship breaking down, so a project that is merely stalled may never trigger them.
Days 4-10: Audit before touching code
The temptation in week two is to start fixing. Resist it. A fix applied before the diagnosis usually lands on a symptom, and it destroys the evidence you needed to find the cause.
Build it on a clean machine
Take a fresh laptop or container, clone the repository, and follow the written instructions exactly as a new developer would. Whether it builds, and how long it takes, tells you more about the project's health in an afternoon than a week of reading will.
Run the tests, and record what does not run
Note the pass rate, but note the coverage gaps harder. A suite that passes in ninety seconds while touching a tenth of the code is a slower way of knowing nothing.
Inventory dependencies and licenses
Produce a full list of third-party packages with their versions, their known vulnerabilities and their licenses. This is the step that turns up inherited legal problems, and the one easiest to defer, because nothing visibly breaks while you ignore it.
Read the data model and restore a backup
Schemas outlive application code. Check that backups exist, then actually restore one into a scratch environment, because an untested backup is a belief rather than a backup.
Map who knows what
For each major area of the system, write down the names of the people who understand it and are still reachable. Blank entries are your real risk register.
That third step tends to produce the surprises. Black Duck's 2026 Open Source Security and Risk Analysis report, which audited 947 commercial codebases across 17 industries, found open source in almost all of them and license conflicts in more than two-thirds (Black Duck, February 2026).1
A license conflict matters more in a takeover than in ordinary development, because the obligation transfers with the code and you did not choose it. A copyleft package pulled into a proprietary product by a developer who has since left is a problem you now own, and one that no amount of refactoring resolves on its own.
The fifth step reads like paperwork and is not. In a 2016 study of 133 popular GitHub projects, Avelino and colleagues found that 65% had a truck factor of two or less, meaning the whole project would be incapacitated if one or two people left (ICPC 2016).2 Open source projects are not offshore contracts, but the shape of the risk is the same, and on a project where the original team has already gone you are measuring what is left rather than what might be lost.
This is also where the cost of a thin handover shows up. Atlassian's 2025 State of Developer Experience survey, which covered 3,500 developers and managers across six countries, found half of developers losing ten or more hours a week to inefficiency, with finding information the single largest drain (Atlassian, July 2025). On inherited code with no documentation, that is not a productivity problem at the margins. It is most of the first month.
Days 11-20: Decide what survives
By day eleven you have findings rather than feelings, and you can make the decision the whole exercise exists for: what to keep, what to repair, and what to build again. Make it explicitly, component by component, rather than letting it emerge from whatever the new team happens to touch first.
Repair what is there
- The build can be reproduced on a clean machine
- Tests exist, even if they are thin
- The data model is sound and the data is intact
- The problems are named, listed and countable
Rebuild that part
- Nobody can make it run outside one developer's laptop
- A dependency is abandoned with no upgrade path
- A license conflict makes the code unshippable as it stands
- The design blocks something the business actually needs
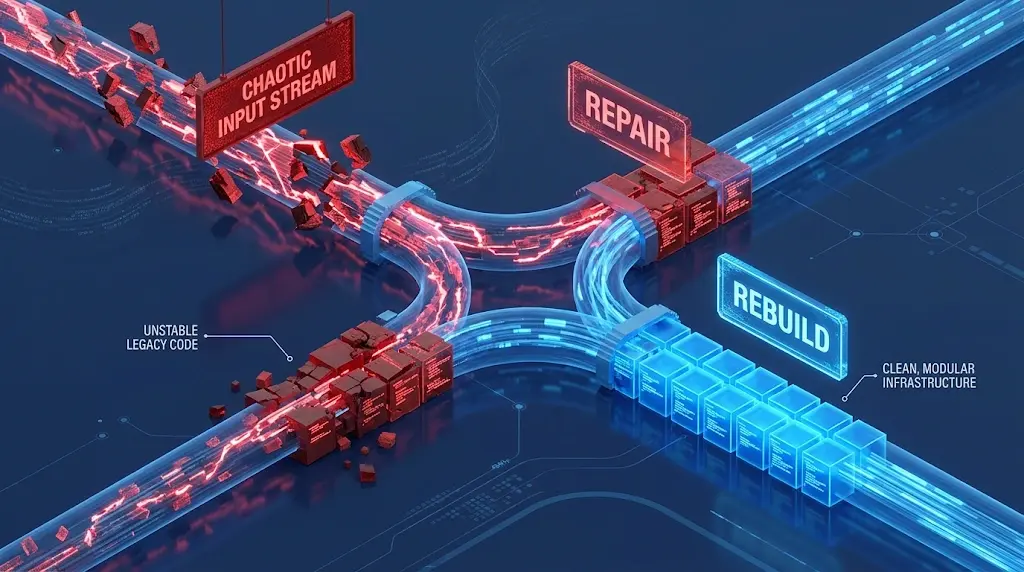
Repair is the default, and the burden of proof sits with rebuilding. A rewrite restarts the clock on every requirement the old code learned the hard way, including the ones nobody wrote down, and it does so at the exact moment your credibility with the business is lowest. Rebuild the specific component you can name a structural reason for, and leave the rest alone. The same rule scales up to whole platforms: replace one part at a time, and keep the old system running until its replacement has earned the traffic. That's how we run digital transformation work.
The debt you are taking on is a budget line rather than a mood. Deloitte's 2026 research on technical debt, which draws on its Global Technology Leadership Study and models the effect with a 63-variable simulation, puts technical debt at 21% to 40% of an organization's technology spending (Deloitte, March 2026). Applied to a project you did not commission, that range is the interest rate on the decision you are about to make.
Be careful using size as a proxy for progress. GitClear's analysis of 211 million changed lines written between 2020 and 2024 found the share of changed lines associated with refactoring falling from 25% in 2021 to under 10% in 2024, while copy-pasted lines rose from 8.3% to 12.3%. In 2024, for the first time on record, cloned code exceeded moved code (GitClear, February 2025). A codebase written recently and quickly may contain far less distinct work than its line count suggests, which cuts both ways: less to understand, and less that was ever designed.
Write the decision down in a page, with the evidence beside each choice. It will be challenged in month two by someone who was not in the room, and the version that survives that conversation is the written one.
Days 21-30: Ship one change
The last ten days prove the pipeline, not the product. Pick the smallest genuinely useful change, and take it the whole way: branch, review, test, deploy, observe, then roll it back deliberately to confirm you can. Everything the earlier weeks found is a hypothesis until a change reaches production under the new team's hands. Fixing delivery before adding capacity matters more than it sounds, because speed applied to an unstable system produces more failures rather than more features.
AI doesn't fix a team; it amplifies what's already there. Strong teams use AI to become even better and more efficient. Struggling teams will find that AI only highlights and intensifies their existing problems.
That finding came from a survey of nearly 5,000 technology professionals, in which 90% reported using AI at work while 30% reported little or no trust in the code it produced. DORA measured AI adoption as positively related to delivery throughput and negatively related to delivery stability, and named the reason plainly: without automated testing, mature version control and fast feedback loops, more change simply means more instability (Google Cloud, September 2025). A recovering project is the clearest case of a team whose existing weaknesses will be amplified by anything that speeds it up.
Record a baseline before the month ends, using DORA's four delivery measures: deployment frequency, lead time for changes, change failure rate, and time to restore service. Only the first can be read from your own month, because it produced a single release. Take the other three from the inherited deployment and incident history, and export that history early, while the old pipeline and its logging accounts are still reachable. The numbers will be unflattering, which is the point, because month two needs something to be measured against.
If the new team works in another time zone, set the handoff discipline now rather than later. What a Kathmandu team looks like from New York works through how a written handover carries a day's context across the gap.
What 30 days will not fix
Thirty days buys a diagnosis, control of your own accounts, a written decision and a pipeline that works. It does not buy a recovered schedule, a cleared backlog or a finished rewrite, and promising any of those to a board is how the second attempt fails the same way the first one did.
Tell stakeholders what the month actually produces, in those terms, on day one. The first month buys a diagnosis, not a recovered schedule. A team that spends thirty days establishing what is true is not a team that has lost thirty days.
Budget for the audit separately from the build. The work of understanding an unfamiliar system is real engineering work, and pricing it as a free preliminary guarantees it gets rushed by whoever absorbs the cost. What offshore software development actually costs breaks down where the money goes on a normal engagement, which is the comparison you need when the recovery quote arrives.
Choosing who takes it over
Whoever inherits this should be willing to be paid for the audit and to deliver a written verdict at the end of it, including the verdict that some of the work should be discarded. A team that quotes a fixed price for a rebuild before seeing the code is either guessing or planning to charge for the guess later. Buying that verdict before anyone commits to a build is what a technology consulting engagement is for.
Ask how they handle the first ten days specifically. A good answer describes reading, reproducing and measuring; a weaker one describes how quickly they can put developers on it. Ask what they would need from you to walk away cleanly in a year, because a partner who has thought about their own exit has thought about your ownership.
Twelve questions that get honest answers from an offshore partner covers the rest of that conversation, and the same questions work better the second time, when you know exactly which answers the last team gave you. If the decision includes where to look as well as who, Nepal against India for software teams compares what the two markets actually offer.
Questions about a stalled project
How do I know whether the project can be saved or should be restarted?
Reproduce the build on a clean machine first. If it builds, the tests run and the data model is sound, repair is the lower-risk path, because a rewrite restarts every undocumented requirement the existing code already handles. Restart only the specific components you can name a structural reason for.
What do I do if the vendor will not hand over the code?
Check the contract for the ownership clause, the termination notice period and any escrow arrangement before escalating, since the answer usually turns on whether ownership was assigned as the work was done or on final payment. Keep paying anything genuinely owed while the dispute runs, because where a contract conditions ownership on payment, stopping payment can hand the other side the argument it needs.
Should I keep the original vendor on during the handover?
A short paid overlap for questions is usually worth it, but revoke their production access at the start of it rather than the end. Written answers to specific questions are more useful than continued commit rights, and the arrangement should have a fixed end date agreed in advance.
How long before a new team is productive on inherited code?
Expect the first month to produce understanding rather than features, and plan for output to stay below normal for a while afterwards. The size of the gap depends far more on whether documentation and tests exist than on the size of the codebase.
Can the project be rescued without the original developers?
Usually, provided the build can be reproduced and the data is intact, because those two things carry most of the knowledge that would otherwise live in someone's head. Where the original developers matter most is undocumented business rules, so budget extra time for anything the code does that nobody can explain.
More questions about how offshore engagements are run are answered on the FAQ page.
The OSSRA figures come from codebases submitted to Black Duck for audit, typically during merger and acquisition due diligence, so they describe software that someone had a reason to examine rather than a random sample of all software. For a project changing hands, that is the closer comparison.
↩Guilherme Avelino, Leonardo Passos, Andre Hora and Marco Tulio Valente, "A Novel Approach for Estimating Truck Factors", 24th International Conference on Program Comprehension, 2016. The corpus is open source rather than commercial, and the study is now several years old, so treat the figure as evidence that knowledge concentration is normal rather than as a rate to apply to your own project.
↩